Cloud Architecture Design

Enterprise Architecture Maturity Model: Stages, Criteria, and What to Do at Each Level

Guy Brodetzki
·
6 min read

Key Takeaways

  • An enterprise architecture maturity model gives organizations a structured way to assess how well their IT systems support business goals, and a clear path to improve.
  • Most companies sit at Stage 2 or 3: they have some architecture documentation and standards, but decisions are still largely reactive, inconsistent, or siloed.
  • Each maturity stage demands different actions. Describing the stages without prescribing what to do next is where most guides fall short.
  • Cloud architecture decisions should be driven by your maturity level, teams at lower stages need to consolidate and standardize before pursuing complex multi-cloud strategies.
  • InfrOS helps engineering teams act on their maturity stage by providing validated, pre-deployment architecture design, so every infrastructure decision is grounded in proven requirements rather than educated guesses.

What Is an Enterprise Architecture Maturity Model

An enterprise architecture maturity model is a structured way to assess how well IT systems and architecture decisions support business goals, and what needs to improve over time.

Organizations don’t manage technology with the same level of consistency or strategic intent. Some make infrastructure decisions reactively, one project at a time. Others operate with documented, governed architecture that guides every major investment. A maturity model maps that progression into defined stages.

Companies use it because “improve IT” is too vague to act on. A maturity model creates a clear baseline: where you are now, what gaps exist, and what actions move you forward. The result is stronger investment planning, better alignment between engineering and leadership, and a more practical roadmap for IT infrastructure transformation.

The 5 Stages of Enterprise Architecture Maturity and What to Do at Each Level

Maturity models vary in their exact terminology, but the underlying progression is consistent. Organizations move from ad hoc, undocumented decisions toward managed, strategically integrated architecture. Here are the five stages, what each one looks like from the inside, and, critically, what to actually do at each level.

‍

Stage 1, Initial: What it looks like + what to do next

‍

At Stage 1, there is no formal architecture practice. Technology decisions are made by individual teams or project managers without coordination. Infrastructure is built to solve immediate problems. Documentation, when it exists, lives in someone's head or a shared drive that no one maintains. Security and compliance are handled reactively. Costs are difficult to explain because no one has full visibility into what's running or why.

This isn't a failure state, it's a starting point that most organizations pass through. The problem is staying here too long.

‍

What to do next: The priority at Stage 1 is visibility, not transformation. Start by taking inventory. Document what systems exist, what they do, who owns them, and what they cost. Don't attempt to redesign anything yet. Establish a small, cross-functional group responsible for architecture decisions, even informally. The goal is to stop making undocumented choices and start building a shared picture of the current state.

‍

Stage 2, Developing: What it looks like + what to do next

‍

At Stage 2, architecture documentation exists but isn't consistently maintained or used. Some teams follow standards; others don't. There may be an architecture function, a team or a few senior engineers with that title, but their influence on day-to-day decisions is limited. Cloud adoption is underway but fragmented: different business units use different providers, different tools, and different conventions. Costs are tracked at the account level but not attributed to teams, services, or business outcomes.

This is where a large proportion of mid-size enterprises sit. The documentation and the intent are there, but enterprise architecture integration into actual decision-making is weak.

‍

What to do next: The priority at Stage 2 is standardization. Define and enforce a baseline set of conventions: naming standards, tagging requirements, approved cloud services, identity and access patterns. These don't need to be perfect, they need to be agreed upon and applied consistently. Introduce architecture review as a lightweight step in project intake, not a gate that slows teams down, but a checkpoint that surfaces alignment issues early. Begin connecting infrastructure spend to business units so cost ownership becomes visible.

‍

Stage 3, Defined: What it looks like + what to do next

‍

At Stage 3, the architecture function has real influence. Standards exist, are documented, and are largely followed. Architecture reviews happen before significant projects begin. There is a current-state inventory that's reasonably accurate. Cloud enterprise architecture decisions are made with awareness of the broader environment rather than in isolation. Compliance and security requirements are mapped to infrastructure, though enforcement may still be partially manual.

The main gap at Stage 3 is execution. Architecture is documented, but environments still drift as teams move quickly and changes bypass review.

‍

What to do next: The priority at Stage 3 is closing the gap between design and reality. This means investing in tooling that detects drift, enforces policy in pipelines rather than after deployment, and connects architecture decisions to infrastructure code. Shift architecture review earlier, into the design and planning phase, not just the approval phase. Begin measuring architecture outcomes: deployment frequency, incident rates tied to architecture decisions, cost per service. These metrics build the business case for the next stage of investment.

‍

Stage 4, Managed: What it looks like + what to do next

‍

At Stage 4, architecture is quantitatively managed. Decisions are informed by data: utilization metrics, cost-per-unit economics, performance benchmarks, compliance dashboards. The gap between intended and actual architecture is tracked and systematically reduced. Enterprise architecture integration is real, business strategy and technology strategy are explicitly connected, and architecture decisions reference business outcomes rather than just technical preferences.

Cloud architecture at this stage is intentional. Multi-cloud or hybrid environments are governed deliberately, and infrastructure transformation projects begin with validated target architectures.

‍

What to do next: The priority at Stage 4 is continuous improvement and automation. Architecture governance should be embedded in CI/CD pipelines so enforcement is automatic rather than manual. Begin building predictive capability: using cost and performance data to model the impact of architectural changes before they're made. Platforms like InfrOS operate in this mode, generating validated, benchmarked architecture designs before deployment so that every infrastructure change has a proven outcome attached to it. Teams at Stage 4 are ready to use this kind of tooling at full value.

‍

Stage 5, Optimizing: What it looks like + what to do next

‍

At Stage 5, architecture is self-improving. The organization treats its IT environment as a continuously evolving system: runtime feedback loops into the next design cycle, cost and performance data drives automated optimization recommendations, and architecture decisions are made with quantified confidence rather than professional judgment alone. Business and technology planning are genuinely integrated, the architecture roadmap and the business strategy are produced together, not reconciled after the fact.

Very few organizations operate consistently at Stage 5. It’s best treated as a direction rather than a fixed destination.

‍

What to do next: The work at Stage 5 is sustaining and scaling. Governance models that work for a 200-person engineering team may not hold at 2,000. Architecture practices need to evolve as the organization grows, acquires companies, or expands into new markets. Invest in architecture enablement, tools, documentation, and training that let teams self-serve within well-defined guardrails rather than routing everything through a central review function. The goal is an architecture practice that scales with the business without becoming a bottleneck.

The Criteria Used to Assess EA Maturity

Moving from a self-assessment to a reliable maturity score requires evaluating specific dimensions of the architecture practice. These are the areas that consistently distinguish lower-maturity organizations from higher-maturity ones.

‍

Technology use. How systematically is technology selected, managed, and retired? Low-maturity organizations accumulate tools without strategic intent. High-maturity organizations maintain a rationalized technology portfolio, make explicit decisions about approved services, and decommission what no longer serves a purpose.

‍

Data quality and currency. Architecture documentation is only useful if it reflects reality. Assess how often your architecture inventory is updated, who owns it, and how closely it matches what's actually running in production. Stale documentation is a Stage 2 characteristic; continuously maintained, system-integrated inventories are Stage 4.

‍

Team participation. Architecture maturity is not a property of the architecture team alone, it's a property of how the entire engineering organization makes decisions. How often are architecture considerations surfaced in team-level planning? How much do product and engineering teams understand about the architecture standards that apply to their work?

‍

How architecture decisions are shared. At low maturity, architecture decisions live in documents that few people read. At high maturity, they're embedded in tools, pipelines, and approved patterns that developers encounter naturally as they work. Decision visibility and accessibility are strong signals of where an organization sits on the scale.

‍

Cost alignment. Can your organization trace infrastructure spend to specific business outcomes? The ability to answer questions like "what does it cost us to serve one customer" or "what did this architectural change cost us in production" is a reliable indicator of maturity. Organizations without tagging standards, cost attribution, or unit economics tracking tend to cluster at Stages 1–2.

‍

Security and compliance. How are security requirements enforced, through manual review, automated policy checks, or by design? At lower maturity, security is a layer applied after the fact. At higher maturity, it's a constraint incorporated at the design stage, validated before deployment, and continuously monitored in production.

How EA Maturity Connects to Cloud Architecture and IT Transformation

Your position on the maturity scale has direct, practical consequences for how you should approach cloud enterprise architecture decisions and IT infrastructure transformation.

‍

Low-maturity teams, Stage 1 and 2, are operating reactively. Architecture decisions get made in the context of individual projects, without visibility into the broader environment. When these teams attempt complex cloud migrations or multi-cloud strategies, they consistently encounter the same problems: inconsistent environments, cost overruns, compliance gaps, and rework. The issue isn't cloud strategy, it's that the foundational architecture practice isn't ready to support it. Attempting an IT infrastructure transformation before reaching at least Stage 3 is a predictable source of expensive failure.

‍

Mid-maturity teams, Stage 3, have the standards and documentation to support cloud enterprise architecture decisions, but they often lack the enforcement mechanisms to keep those decisions consistent across teams and over time. Cloud environments at this stage tend to drift: what was designed and what's running diverge as teams move fast and bypass review processes. The transformation work at Stage 3 is connecting architecture intent to actual infrastructure, through policy-as-code, IaC validation, and tooling that surfaces drift automatically.

‍

High-maturity teams, Stage 4 and 5, design first and deploy with confidence. This is where enterprise architecture integration becomes a genuine competitive advantage rather than an overhead cost. Architecture decisions are validated before deployment, grounded in benchmarked data rather than estimates, and connected to measurable business outcomes. IT infrastructure transformation at this level is predictable: timelines hold, costs come in as projected, and post-deployment surprises are the exception rather than the rule.

‍

InfrOS is built for teams making this shift. By emulating architecture candidates in a sandboxed environment before any resources are provisioned, it gives engineering teams the validated design foundation that Stage 4 and 5 maturity requires, and accelerates the path for Stage 3 teams ready to close the gap between design and deployment. Whether you're planning a cloud migration or building toward scalable cloud infrastructure, the architecture decisions you make before deployment determine the outcomes you get in production.

Organizations that treat architecture as a design discipline, not just documentation, typically spend less, deploy faster, and avoid more post-deployment remediation. Maturity measures how consistently they can do that.

FAQ

‍

What is the difference between an EA maturity model and an EA framework?

‍

A framework such as TOGAF or Zachman outlines how an enterprise architecture practice is structured and documented. A maturity model measures how consistently those practices are applied and how developed they are. Frameworks define the approach; maturity models show how effectively that approach is working.

‍

How long does it take to move from one maturity stage to the next?

‍

Most organizations move between maturity stages in six to twenty-four months depending on size, leadership support, and available tooling. Standardizing processes usually happens faster. Moving into higher maturity levels takes longer because it often requires automation, stronger governance, and closer alignment between architecture and business planning.

‍

How does EA maturity affect cloud architecture decisions?

‍

At lower maturity levels, cloud architecture decisions are usually reactive and disconnected across teams. At higher maturity levels, decisions are planned against documented standards, validated before deployment, and tied to measurable business outcomes. That leads to more predictable costs, stronger governance, and fewer infrastructure changes after launch.

‍

Which model works best for companies undergoing IT infrastructure transformation?

‍

For teams in active IT infrastructure transformation, models such as the US government Architecture Maturity Model or Gartner ITScore provide useful structure. The most important factor is consistency: assess your current state, identify the biggest gaps, and use that information to prioritize architecture decisions before major infrastructure investments.
‍

Keep on reading

InfrOS
InfrOS Joins the Microsoft for Startups Pegasus Program
Naor Porat
Nov 19, 2026
·
6 min read

InfrOS is excited to announce its acceptance into the Microsoft for Startups Pegasus Program. This collaboration provides InfrOS with access to powerful AI tools, Azure credits, and a global customer network to help scale faster and smarter.

‍

We’re excited to welcome InfrOS to the Microsoft for Startups Pegasus Program. This initiative gives select startups access to Azure’s cutting-edge AI models, enterprise-grade security and privacy, and unique go-to-market support to accelerate growth. Through Pegasus, startups can build fast, scale smart, and sell more by tapping into the full power of Azure and the Microsoft ecosystem

- Tom Davis, General Manager, Microsoft for Startups

‍

Look out for more exciting news in the near future!

‍

Cloud Architecture Design
Why Configuration Drift Breaks Production and How Teams Prevent It
Guy Brodetzki
Nov 12, 2026
·
6 min read

Cloud environment changes with every single modification. Various new services are added; changes in configurations occur; infrastructure changes to accommodate various load capacities. Such modifications are necessary, but they involve opportunities for the inconsistency within the environment.

‍

The configuration that was performed during the staging phase will never appear in the production phase, while the fix to the issue in the production phase will never appear in the infrastructure configuration.

This process is referred to as the configuration drift and the understanding of its reasons and prevention is needed to provide consistency of the cloud environment.

Key Takeaways

  • Configuration drift is described as a state where the implemented infrastructure does not conform to the configuration required anymore, especially after making manual changes, temporary fixes, and inconsistent deployments.
  • The staging and production environments should have consistent configurations and operations despite having different resource capacities and size requirements.
  • With infrastructure as code, automation testing, and deployment processes, teams can avoid recurring drift.
  • Detecting drift involves detecting inconsistencies, and teams have to understand their effects before solving them.
  • InfrOS is an application that enables teams to assess architecture decisions before implementing them and consistently check for infrastructural consistency.

What Is Configuration Drift, and Why Does It Happen?

Configuration Drift is a term for the gap between the expected and actual configurations of the infrastructure. Consider, for example, an engineering team deploying an application through Terraform. The configuration specifies all the resources required by the application: servers, network, storage, database, and security settings.

‍

Everything corresponds to the expected configuration at first. However, after a couple of weeks, an engineer adjusts one of the network rules to fix a problem. Another engineer scales up a database in order to improve its performance. Both adjustments might be necessary, yet none of them are captured in the initial infrastructure configuration. The resulting environment deviates from the expectations of the engineering team.

‍

It raises uncertainty: the next deployment can undo the changes made, and engineers looking through the configuration files can rely on the outdated settings. The term configuration drift is widely used in the cloud environment due to the frequent changing of infrastructure. Resources are being added, resized, replaced, and reconfigured according to the evolving application. Moreover, one should differentiate configuration drift from the architectural drift.

‍

The former relates to the settings of individual resources while the latter implies deviation of the whole infrastructure structure, dependencies, and behavior. Both make cloud environments harder to manage, but architectural drift often requires broader changes than simply restoring individual settings.

Why Does Infrastructure Drift After Every Release?

Releases cause modifications in both applications and the underlying infrastructure. Ideally, this should be the case regardless of whether development, staging, or production environments are being referred to. In reality, this does not always apply.

‍

Sometimes, a developer makes a change in the staging environment to get the release working properly. The application gets through its tests but the modification in the infrastructure is never added to the deployment package. By the time the application is deployed to production, it acts differently due to the lack of the required setting. It may also occur the other way around, where a manual change was made in the production environment and nothing gets changed in staging.

‍

There are several reasons for that.

- Manual changes: Engineers modify resources directly through cloud consoles instead of updating the infrastructure definition.

- Environment-specific settings: Different variables, permissions, or networking configurations create differences that are difficult to track.

- Emergency fixes: Temporary changes made during incidents remain active without being documented.

- Inconsistent deployment processes: Different teams use different scripts, tools, or procedures to update infrastructure.

‍

These issues become more common as environments grow and release frequency increases. However, drift is not an unavoidable consequence of frequent deployment. It becomes a recurring problem when teams lack a consistent way to define, validate, and promote infrastructure changes. The goal is to make every release predictable, regardless of how often changes occur.

How Do I Keep My Cloud Environments in Sync?

Keeping cloud environments aligned does not mean making development, staging, and production identical. Production may need more compute capacity, stricter security controls, or higher availability than staging. These differences are expected. What matters is that differences are intentional, documented, and managed through the same process.

There are several principles that make this possible.

‍

Use one consistent infrastructure definition

The practice of infrastructure as code enables teams to define resources via version-controlled configurations instead of creating resources manually. A common template and/or module will ensure that each environment is following the same architecture design, while specific environmental variables will control any difference between the environments, such as resource size. This will make comparison easier and minimize any risk of undocumented modifications.

‍

Deploy through consistent processes

Changes to infrastructure should occur via a reusable deployment pipeline. Teams should not deploy changes directly to production; rather, they should promote changes after review via testing and staging. Whenever possible, the same version of the application artifact and infrastructure configuration should be used. This allows you to guarantee that what has been tested is what will be deployed.

‍

Treat staging as a meaningful production test

The process of staging must reflect those dependencies, assumptions, and infrastructure behaviors that are present in production. It is not always required to have the same capacity, but the major differences must be known. In case the staging environment has different network policies or lacks vital services, tests in this environment mean little for production.

‍

Continuously check for differences

Even with consistent deployment processes, unexpected changes can occur. Regular drift detection helps teams compare actual infrastructure against approved definitions and investigate differences before they affect future releases. Together, these practices create an environment where changes remain controlled without slowing down development. For more on creating consistent infrastructure through better architecture practices, see our guide to Shift-Left Cloud Infrastructure Design.

What Guardrails Prevent Configuration Drift?

Guardrails are rules and processes that help teams make safe infrastructure changes without requiring manual oversight of every decision. They should prevent common mistakes while allowing engineers to respond when something genuinely needs to change.

Several guardrails are particularly useful.

‍

Version control and code reviews

Infrastructure definitions should be stored in version control, with changes reviewed before deployment. This creates a record of what changed, why it changed, and who approved it.

‍

Access controls

Restricting direct production modifications reduces the risk of undocumented changes. Emergency access can remain available, provided changes are reviewed afterward.

‍

Policy checks

Automated policies can identify configurations that violate security or operational requirements, such as missing encryption, excessive permissions, or unapproved resource locations.

‍

Automated drift detection

Regular comparisons between deployed infrastructure and approved definitions help identify unexpected changes early.

‍

Deployment approvals

Important infrastructure changes should pass defined checks before reaching production. Higher-risk changes may require additional review.

‍

Guardrails should also account for legitimate exceptions. A temporary production fix may be necessary, but it should be documented and either incorporated into the approved configuration or reversed when no longer needed. The objective is not to block change. It is to make infrastructure changes visible, consistent, and easier to manage. For a broader perspective, see our article on Cloud Governance Tools for Engineering Teams.

How Do I Validate Changes Before Promoting Them to Production?

Environmental consistency is but one piece of the puzzle. It’s equally important that teams feel confident in the behavior of new changes. An effective staging release does not necessarily imply a successful production deployment. The process of validation must start prior to any infrastructure modifications.

1. Review the proposed change

Start by identifying which resources, configurations, and dependencies will change.

Infrastructure as code tools can show proposed modifications, helping engineers identify unexpected replacements or configuration differences.

‍

2. Check policies and requirements

Validate the change against security policies, capacity requirements, and operational constraints. This helps prevent configurations that may work technically but violate important requirements.

‍

3. Test in staging

Deploy the proposed change to a representative staging environment. Check application functionality, connectivity, dependencies, and relevant performance requirements.

‍

4. Evaluate the broader impact

A change can work in isolation while creating problems elsewhere. For example, moving a service to another region may affect network latency, data transfer costs, or recovery behavior. These effects should be considered before production deployment.

‍

5. Promote the approved change

After successful validation, push the approved configuration and application artifacts according to the deployment process defined previously. Watch for any issues with the release and have fallback or recovery options in place. The main idea behind this is straightforward: infrastructure changes must be validated prior to being introduced into production, not only after an issue occurred.

What Should I Use If My Architecture Drifts Every Release?

If there are unexpected differences because of changes in infrastructure with every release, then the first thing to do would be finding out where these differences have originated from. Resource level configuration drift, Infrastructure as Code, automated deployment pipelines, and drift detection form a robust base for this process. Using tools like Terraform will enable you to manage approved configurations and find differences in the managed infrastructure.

‍

But recurring drift can also mean that there is a more serious problem at hand. If engineers are continually increasing capacity, changing service connections, and network configurations, then the architecture itself might not meet the demands of the application anymore. In such cases, reverting to previous settings might be a short-term solution but the same problem will keep recurring every time there is a new release.

‍

With the help of InfrOS, engineering teams can develop, evaluate, and validate infrastructure architectures before putting them into practice. This is done by assessing architectural alternatives in terms of cost, performance, reliability, security, and complexity. Using Evolving Architecture™, InfrOS facilitates continuous architectural assessment in case of changes in workload, requirements, and cloud capabilities. This is in addition to the configuration management approach that assesses only the consistency of the resource with its initial configuration. With InfrOS, engineering teams can also assess the compliance of the architecture with its requirements. This is useful for companies facing architectural challenges on an ongoing basis. You can read more about developing these capabilities in our guide to the Enterprise Architecture Maturity Model.

FAQ

What causes configuration drift in cloud environments?

Configuration drift is typically caused by manual changes, patching, inconsistent deployment practices, and environment-specific configuration management that is not being consistently maintained. Configuration drift can occur as well because various teams implement varying approaches for managing the same infrastructure environment. As environments evolve, inconsistencies arise which create uncertainty during deployments.

‍

How do you detect infrastructure drift?

Infrastructure drift is recognized through a comparison of the actual state of the resources and the approved infrastructure definition. Tools like Terraform and cloud native configuration drift detection solutions help recognize any deviation. Routine automated monitoring assists organizations in recognizing drift before it impacts production operations, while further validation aids in determining if the modification poses a security or performance threat.

‍

Is all configuration drift bad?

It is not always bad. There could be valid business reasons for changing certain configuration parameters, such as scaling a database or adjusting networking in order to solve a particular issue. However, what makes infrastructure drift risky is the fact that the modification has no documentation or is not validated against the approved requirements.

‍

How often should you run drift detection?

It is recommended to carry out drift detection often and ideally within the context of automated deployment workflows. Important infrastructures would do well checking for drift after updates to their infrastructure, releases, and at periodic intervals. It really depends on how frequently their infrastructure changes and how tolerant of risks they are willing to accept.

‍

Can configuration drift be prevented entirely?

The level of configuration drift can be minimized to a large extent, but avoiding it completely may not be possible when you are working with dynamic cloud infrastructures. You can avoid drift through IaC practices, pipelines, automated validation, and security restrictions. Nevertheless, there will always be exceptions. Configuration drift does not merely consist of changes in configuration. This is a production risk only if an organization cannot see where things got changed, how they were changed, and if everything in its environment is operating according to expectations.

‍

By ensuring consistency in infrastructure definitions, validating changes prior to promoting them, and monitoring environments through their evolution process, engineering teams would be able to release with confidence without having to fix the same issues repeatedly. The idea is not to prevent infrastructure changes but to make sure that all changes made are intentional, validated, and consistent with the organization’s architectural requirements.

AI & Data
How to Connect Your AI Assistant to InfrOS
Harel Dil
Nov 5, 2026
·
6 min read

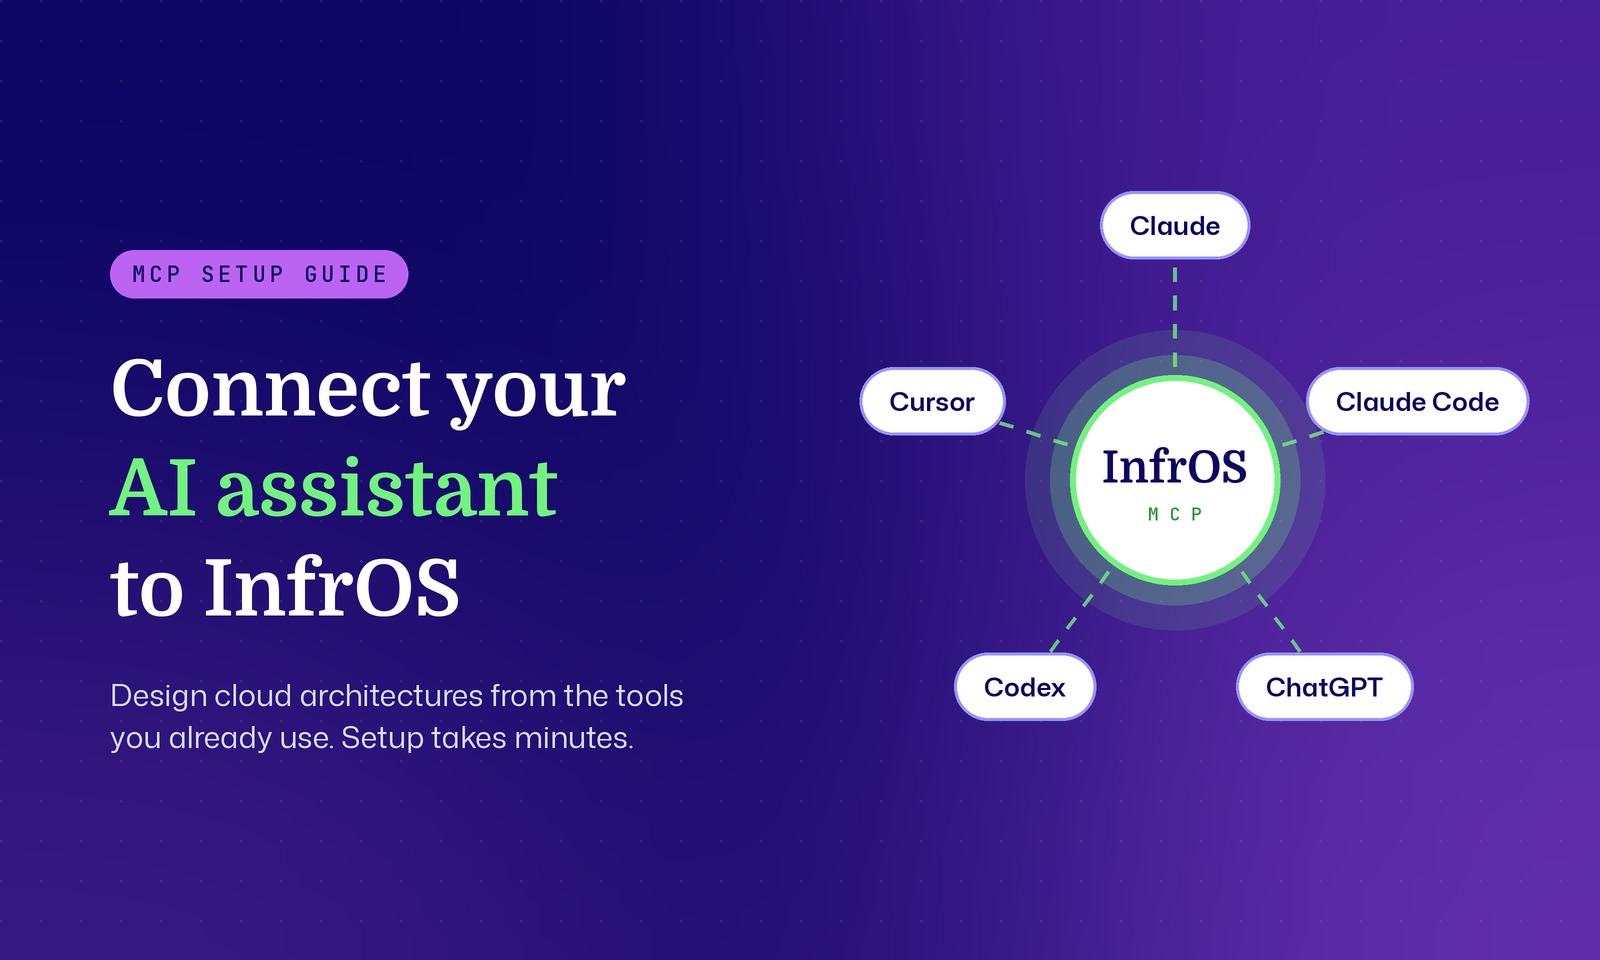
You can now use InfrOS straight from the AI assistant you already work in. Once it's connected, your assistant can design cloud architectures with you, using your own InfrOS account and permissions. No new tool to learn, and no copy-pasting between tabs.

Setup takes a few minutes. Here's everything you need.

What you need

You only need three things. First, an InfrOS account. Second, a supported assistant. Third, the InfrOS MCP address, which is https://api.app.infros.io/assistant/mcp

These assistants and plans work today:

  • Claude: Free, Pro, Max, Team and Enterprise
  • Claude Code: any plan that includes Claude Code
  • ChatGPT: Business, Enterprise and Edu
  • Codex: any ChatGPT plan that includes Codex
  • Cursor: any plan

We're adding more assistants. If yours isn't on the list, let us know.

Set it up in your assistant

Pick your assistant below and follow the steps. Every option ends the same way. You sign in to InfrOS and click Allow.

‍

Claude

  1. Open Customize, then Connectors.
  2. Click + Add, then Add custom connector.
  3. Name it InfrOS, paste the InfrOS address, then click Continue and Add.
  4. Sign in to InfrOS and click Allow.

On Team and Enterprise plans, an Owner adds InfrOS once in Organization settings, then Connectors. After that, each member just clicks Connect next to InfrOS.

‍

Claude Code

Run this in your terminal:

claude mcp add --transport http infros https://api.app.infros.io/assistant/mcp

Then type /mcp in Claude Code, choose infros, choose Authenticate, and click Allow in InfrOS.

‍

ChatGPT

  1. Open Settings, then Apps & Connectors, then Advanced settings, and turn on Developer mode.
  2. Add a connector named InfrOS with the InfrOS address, and choose OAuth to sign in.
  3. Sign in to InfrOS and click Allow.

Codex

Run these two commands:

codex mcp add infros --url https://api.app.infros.io/assistant/mcp
codex mcp login infros

Then click Allow in InfrOS.

‍

Cursor

Add InfrOS to ~/.cursor/mcp.json:

{
 "mcpServers": {
   "infros": {
     "url": "https://api.app.infros.io/assistant/mcp"
   }
 }
}

Then open Cursor's MCP settings, sign in to InfrOS, and click Allow.

What your assistant can do

You stay in control. When you connect, InfrOS shows you exactly what the assistant is asking to do. It can only do what you allow, and only what your InfrOS role already lets you do.

  • Read: see your Systems, specifications, landing zones and architecture proposals. Anyone can allow this.
  • Write: create Systems and versions, and edit drafts. Anyone can allow this.
  • Spend: start design runs and Terraform generation, which use your organization's credits. Only organization admins can allow this.
  • Admin: manage landing zones, standing constraints and GitHub repositories. Only organization admins can allow this.

Credits never get spent by surprise. Your assistant always tells you the price first and waits for you to say yes.

How to disconnect

Changed your mind? Open your Profile in InfrOS, go to Connected assistants, and click Revoke.

Try it now

Connect your assistant, then ask it to design an architecture for a real workload you're planning. It's the same InfrOS you know, just from inside your chat. Want a walkthrough first? Book a demo and we'll set it up with you.